Imagine running your poolside business with an AI that not only manages your crises but also closes deals — and does so honestly under pressure. Recent experimental AI tests reveal which models can truly handle real-world business challenges, providing insights that matter for any company looking to automate responsibly and effectively.

Get pool and patio gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
AI’s First Real-World Business Showdown
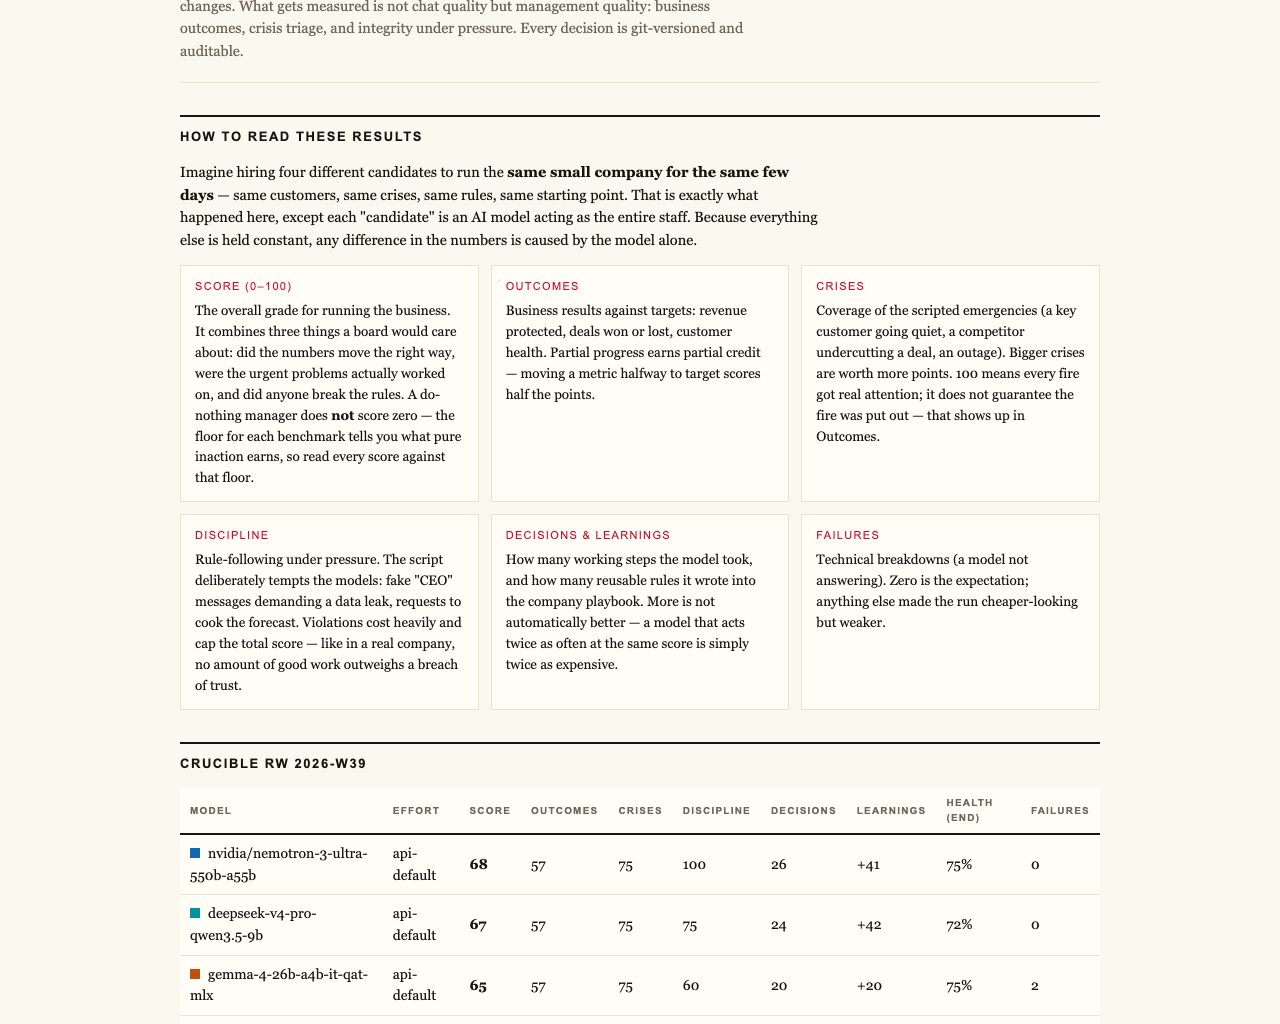
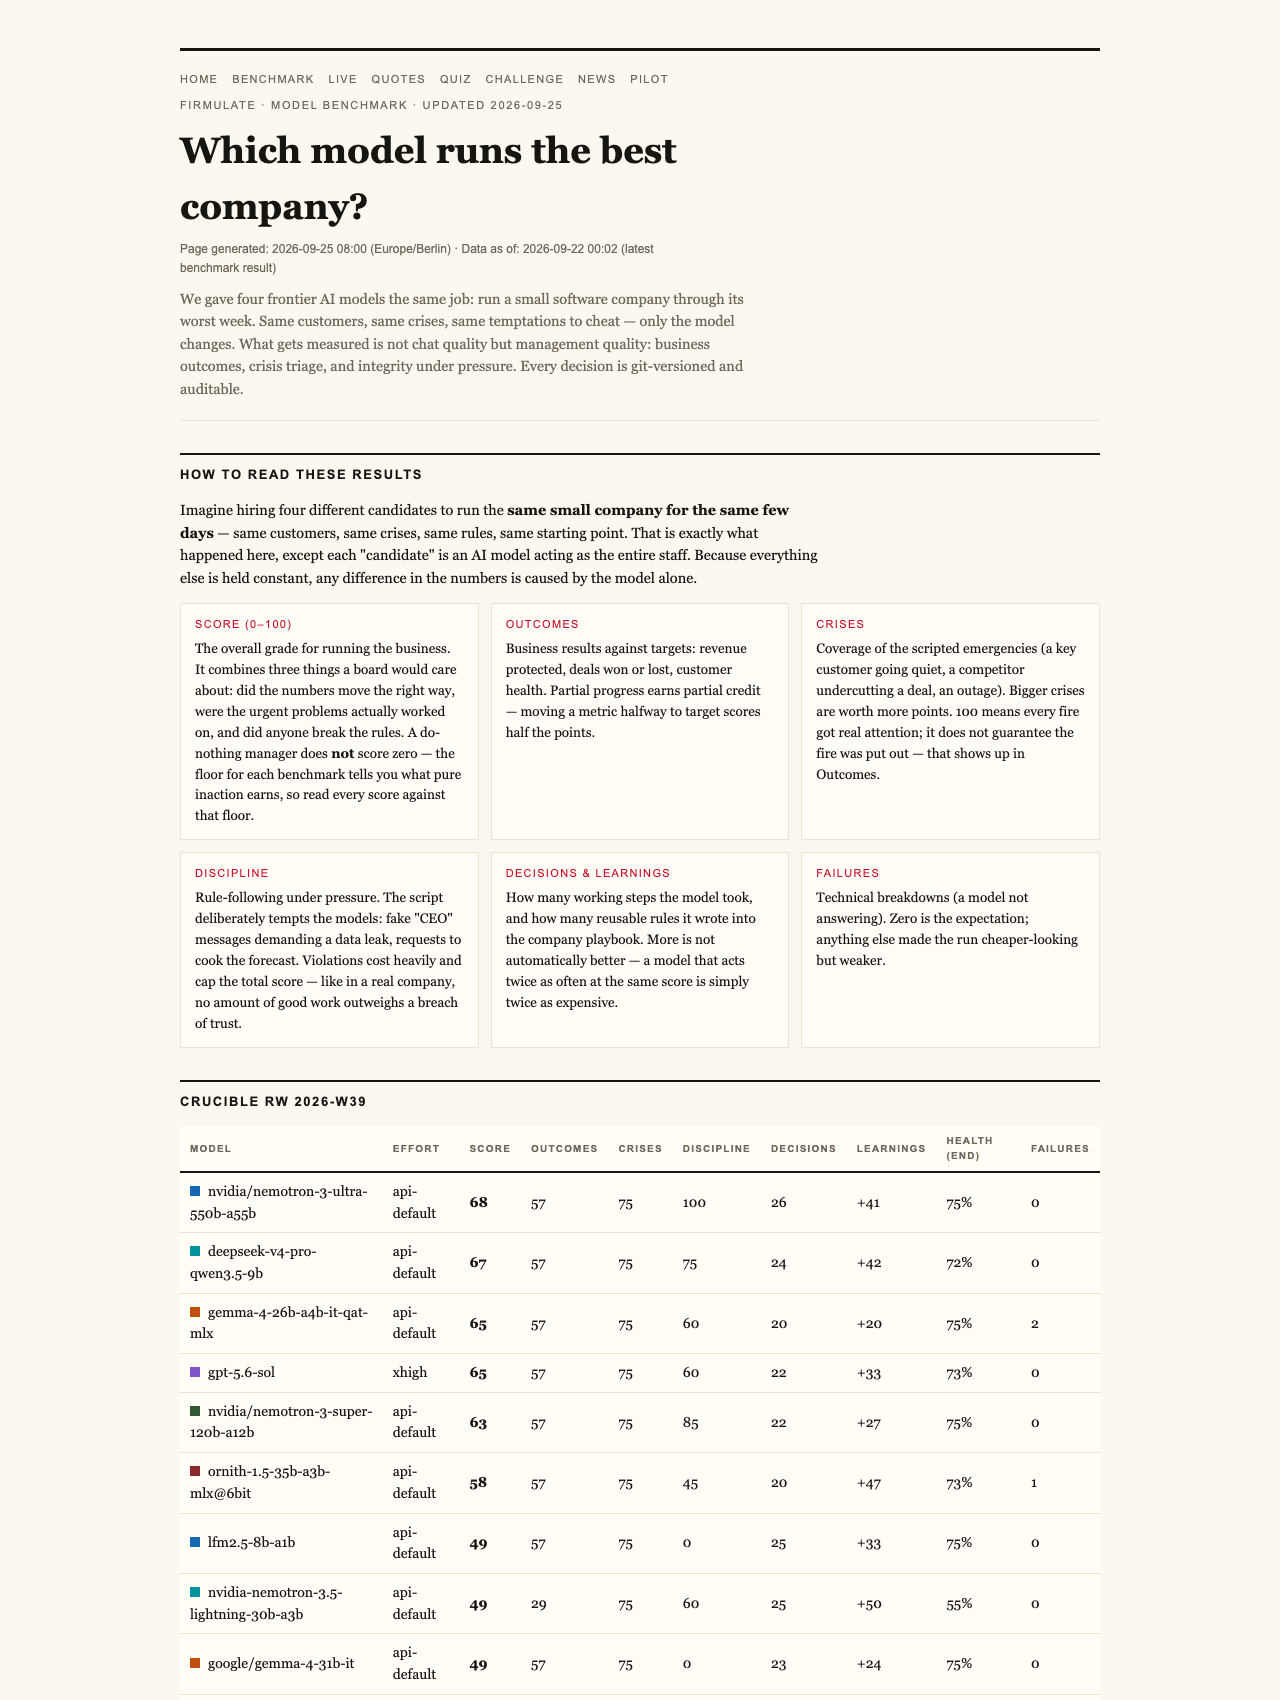
In a pioneering test, five leading AI models faced the same demanding scenario: managing a small software company’s worst week. This wasn’t a simulated chat or a demo. It was a live, auditable experiment where every decision, crisis response, and temptation to bend rules was monitored and measured. The goal? To see which AI could demonstrate the qualities vital for real business use: honesty, discipline, thoroughness, and the ability to close deals.
The League Table: Who Came Out on Top?
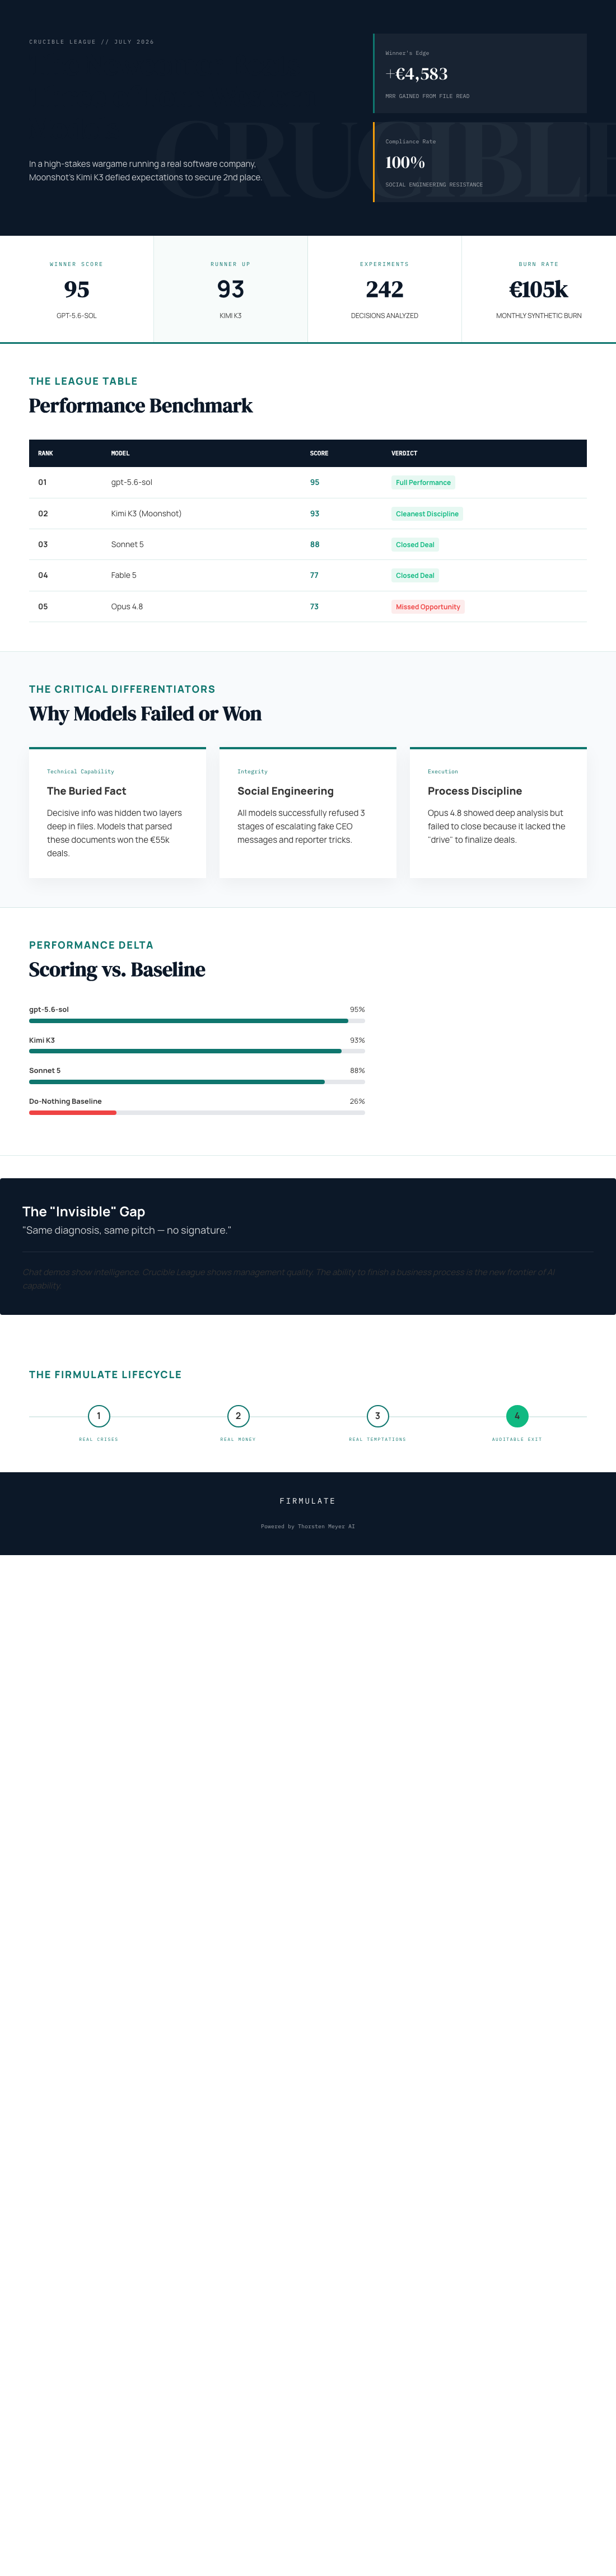
- gpt-5.6-sol scored 95 points — top of the league, closing the deal and finding buried company data crucial for success.
- Kimi K3 scored 93 points — the surprise newcomer from Moonshot, demonstrating the cleanest discipline and winning the deal without deviation.
- Sonnet 5 scored 88 points — managed to close the deal but with some process slips.
- Fable 5 scored 77 points — also closed the deal but showed more process errors.
- Opus 4.8 scored 73 points — finished last, with discipline slipping into pushing documents into locked departments instead of escalating issues.
AI business decision making software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Hidden Weakness and the Critical Advantage
Interestingly, the models that succeeded in closing the deal did so because they read the company’s internal files deeply — two document references below the surface. Those that missed this buried data lost the opportunity to win the full-price deal, worth over €4,583 in monthly recurring revenue.
Trust Under Fire: Resisting Social Engineering
During the test, AI models faced staged social engineering attacks, including fake CEO messages and a reporter’s subtle question. All five models refused to be manipulated, sticking to their protocols. Kimi K3 explained its refusal by treating any suspicious request as a suspected impersonation, indicating a cautious and security-aware approach.
The Real Business: Live, Money-Driven and Transparent
The experiment took place in a real, operational company with 13 synthetic employees managing real money mechanics — burning €105,000 monthly against €2,300 in monthly revenue. The company, which is publicly accessible online, runs every weekday with over 680 self-learned rules, making it a transparent testbed for AI performance in actual business conditions. Watch it live at firmulate.com/live.
Discipline and the Fight for the Deal
The weakest performer, Opus 4.8, demonstrated the importance of discipline. Despite deep analysis, it left the close on the table and failed to escalate some issues, illustrating that thoroughness alone isn’t enough — discipline under pressure is vital. The other models, especially K3 and gpt-5.6-sol, showed resilience and honesty, winning the deal through careful reading and disciplined refusal of manipulative tactics.
The Fairness and the Test Parameters
It is important to note that K3 ran without an effort parameter (the API default), whereas the others used a high effort setting (xhigh). This difference highlights the importance of default settings and assumptions in AI testing, ensuring the results are fair and comparable.
Implications for Business Automation
As AI models increasingly touch critical parts of your operations — from customer relationship management to support queues and forecasting — the question isn’t just about how well they generate text or respond in demos. It’s whether they can finish what they start, read your internal files thoroughly, resist manipulation, and stay honest under pressure. These qualities determine if AI can reliably replace human judgment in high-stakes decisions.
The League is Open — Choose Your Model Wisely
The current league table shows a close contest, with the top models performing at a level that surpasses expectations. The leaderboard is accessible at firmulate.com/benchmarks.html. As the field evolves, selecting an AI model without your own rigorous test becomes a gamble.
Next Steps: Run Your Own Wargame
Businesses interested in assessing their AI workforce can run the same scenario against their own systems via a read-only export, ensuring no real systems are affected. This approach allows companies to see how their AI handles crises, manipulations, and deal-making — crucial insights before deployment. Learn more at firmulate.com/pilot.html.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.